Skip to content
Synapse Horizon

GPU Servers & Racks

GPU servers and AI racks for on-premise private AI

Enterprise and datacenter-grade GPU servers, high-density racks and the storage and management nodes around them, for organisations that run AI on their own premises and keep sensitive data in-house.

Node sizes
1–8 GPUs
Rack density
Up to 100 kW+
Deployment
On-premise
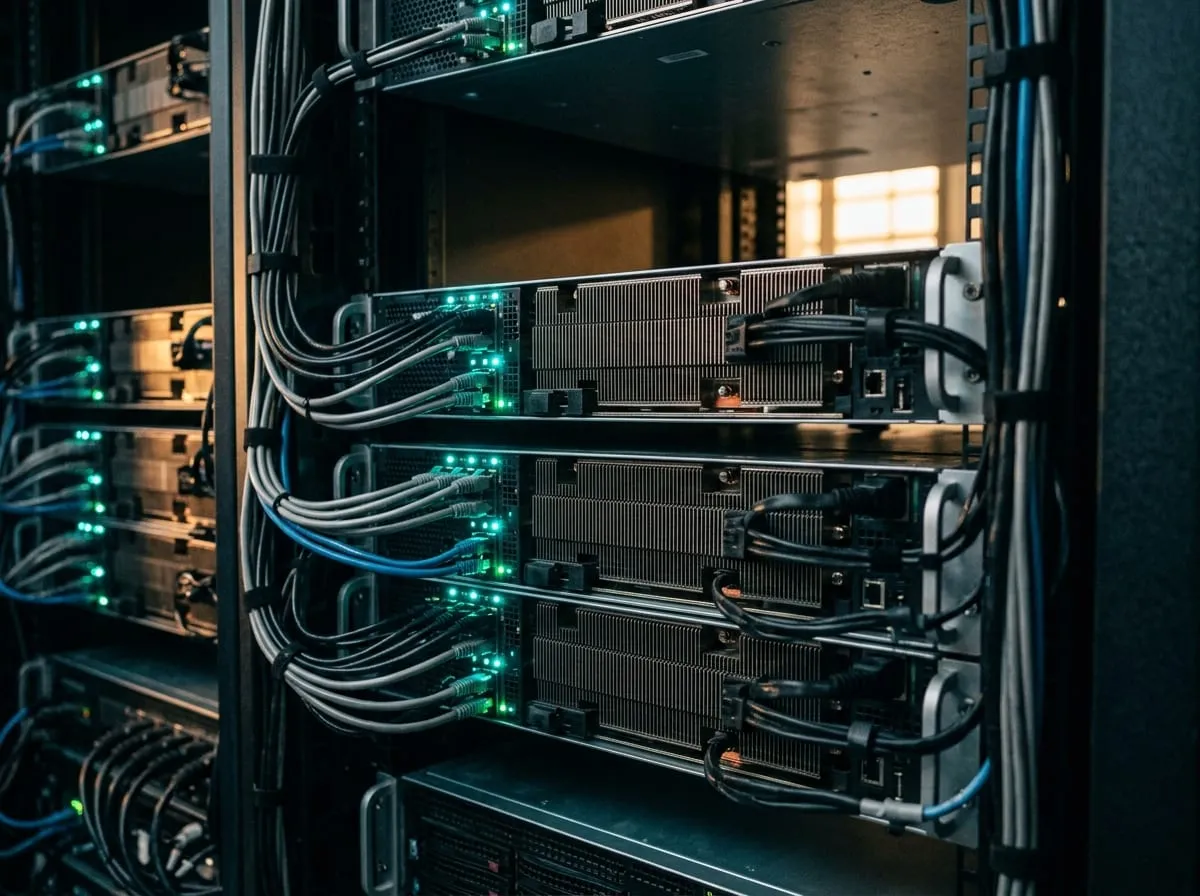
Rack of high-density GPU servers with neat cabling and teal status lights

What we supply

GPU Servers & Racks product groups

Wholesale supply in project and container volumes. Tell us your specification and we source to it.

GPU servers and AI compute nodes

Enterprise and datacenter-grade servers for inference, fine-tuning and training.

  • 1-, 2-, 4- and 8-GPU nodes with datacenter accelerators and high-bandwidth memory
  • High-speed GPU-to-GPU interconnect for multi-GPU training
  • PCIe Gen5 platforms with dual-socket server CPUs and large system memory
  • One high-speed network adapter per GPU for scale-out clusters
  • Redundant hot-swap power supplies, in air-cooled or liquid-ready variants
Quote this: GPU servers and AI compute nodes

High-density racks for training and inference

Racks, containment and cable management built for AI power and weight.

  • 42U–52U racks with high static load ratings for dense GPU nodes
  • Air-cooled layouts to around 30–40 kW per rack; liquid-cooled designs beyond 100 kW
  • Rear-door heat exchanger and in-rack liquid manifold options
  • Hot- and cold-aisle containment kits
  • Structured cabling trays for high-count optical and copper links
Quote this: High-density racks for training and inference

Storage and management nodes

The data and control layer that keeps GPUs busy and the cluster manageable.

  • All-flash NVMe storage nodes for training datasets and vector databases
  • Scale-out file and object storage for model and document archives
  • Login, scheduler and management nodes
  • Out-of-band management over IPMI and Redfish
  • Backup and checkpoint targets sized to your retention policy
Quote this: Storage and management nodes

Applications

Where it is used

01

Private LLM inference

Run large language models on your own servers so prompts, documents and outputs never leave your network. Inference sizing depends on model size, numeric precision, context length and concurrent users. One well-specified GPU server can serve a department, and clusters scale to enterprise-wide assistants.

02

Retrieval over internal documents

Retrieval-augmented generation connects a model to your contracts, policies, records and manuals. This combines GPU inference with fast NVMe storage for vector search. Keeping the whole pipeline on-premise supports data-residency and confidentiality obligations in banking, healthcare, legal and government work.

03

Fine-tuning and training

Adapting open models to your language, terminology and workflows needs multi-GPU nodes with fast interconnect and a high-throughput storage tier. Larger training runs span several nodes on a low-latency fabric. Our partners size the cluster to your datasets and target training time.

04

Computer vision and analytics

Video analytics, document OCR and inspection models run efficiently on GPU servers in your own datacenter or server room. Central GPU nodes can process feeds from many cameras, while edge devices handle latency-critical tasks close to where the data is produced.

Why Synapse Horizon

Supplied by us, delivered with our partners

Tier-1 sourcing

Servers, racks and storage sourced from Tier-1 enterprise hardware manufacturers and authorised channels, with the manufacturer warranty applying.

Documentation and compliance support

Datasheets and safety certificates available on request, and export-control questions raised early, so procurement and security reviews do not stall delivery.

Logistics coordinated from Dubai

Shipments can be consolidated in Dubai and delivered by road or sea across the UAE, Saudi Arabia, Oman, Qatar, Kuwait and Bahrain, and onward to wider MENA.

Partner integration and deployment

Our integration and AI-deployment partners handle site survey, racking, cabling, burn-in and software stack set-up, so hardware arrives as a working system.

FAQ

GPU Servers & Racks questions

How many GPUs do I need for a private LLM?
It depends on model size, precision and concurrent users. As a rough guide, a model’s weights need about two bytes per parameter at 16-bit precision, so a 70-billion-parameter model needs around 140 GB of GPU memory before cache and overhead. Quantisation reduces this. Our partners size the system from your real workloads.
Can you supply a complete, ready-to-run system?
Yes. We can supply the GPU servers, racks, storage, networking and power as one coordinated order. Our integration and AI-deployment partners then install, cable, burn in and configure the software stack, including the operating system, drivers, orchestration and model serving. If you prefer a starting point, see our AI hardware bundles.
How much power and cooling does a GPU server need?
An 8-GPU training node can draw on the order of 10 kW at full load, so a few nodes quickly exceed what a typical office server rack supplies. Check rack power feeds, UPS capacity and cooling before ordering. For dense deployments, liquid cooling is often the practical route, especially in Gulf ambient conditions.
Are high-end GPUs subject to export controls?
Yes. Some advanced accelerators are subject to export-control licensing, and requirements differ by product and destination. We can raise this at the start and collect end-user and end-use information, so eligibility is clear before you commit. Timelines for controlled items can be longer, so involve procurement early.
Why run AI on-premise instead of in the cloud?
On-premise AI keeps sensitive data inside your own network, which simplifies compliance with data-protection laws, sector regulators and internal policy. Costs are predictable for steady workloads, and latency to internal systems is low. It needs space, power, cooling and operations skills, which our deployment partners can provide.

Request a quote

Request a quote for GPU Servers & Racks

Share quantities, specifications, delivery location and timeline. No obligation, and we reply within one business day.