Private AI bundles
On-premise AI server bundles, sized to your team
Synapse Horizon supplies three on-premise AI server bundles for running private LLMs, from a single-team workstation to a rack-scale cluster. We supply the hardware from Dubai to the UAE and GCC; our partners install it, deploy open-weight LLMs and support it. Every bundle is quoted to your requirements.
User counts and model sizes are indicative. Actual capacity depends on concurrency, context length and workload, and is confirmed in your proposal.
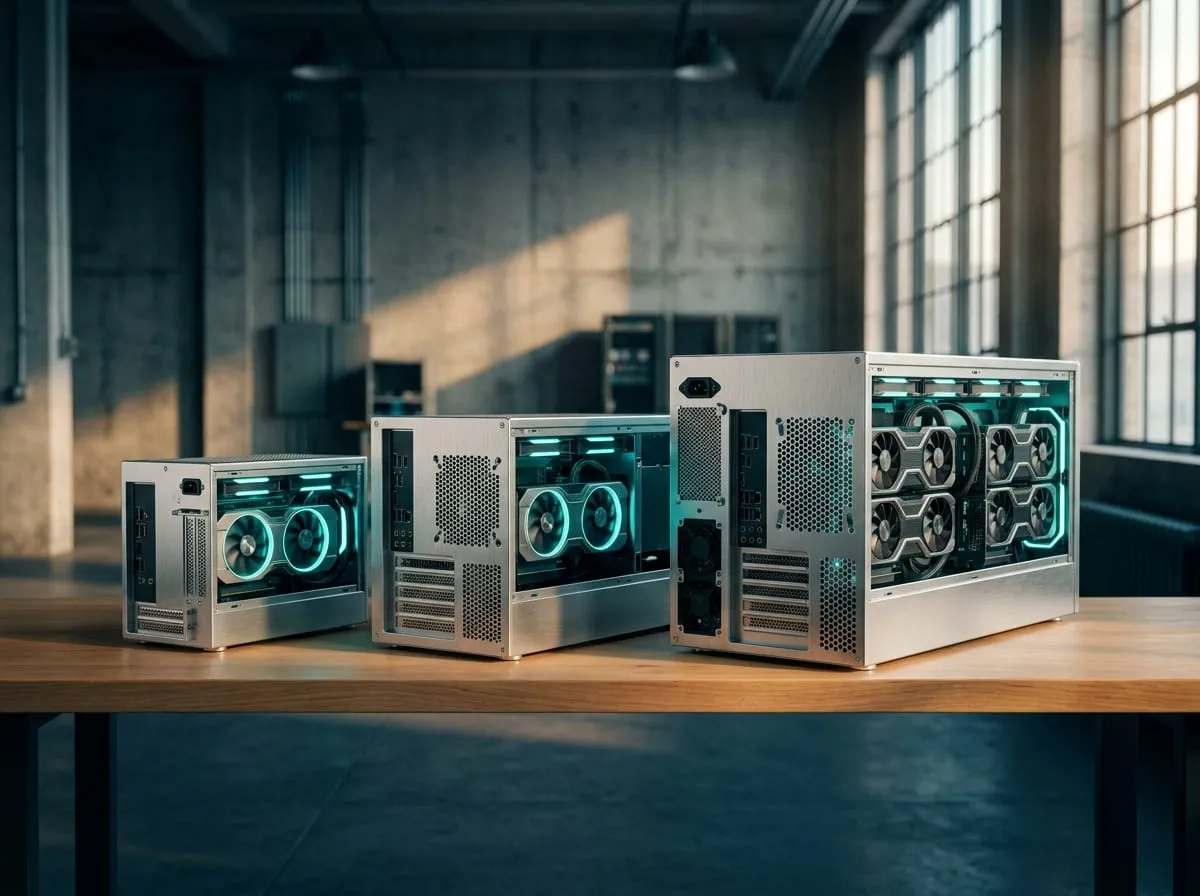
Typically 5–25 users
Team bundle
A first private AI deployment for one team, practice group or pilot project.
- Typical users
- 5–25 users
- Typical models
- Open-weight LLMs of 7B–14B parameters, quantized
- GPU class
- 1–2 professional GPUs
- Storage
- Local NVMe
- Form factor
- Workstation or 2U–4U server
What’s included
- A 1–2 GPU workstation with professional GPUs, or a compact rack server
- Enough GPU memory to serve 7B–14B-parameter open-weight models, quantized
- Local NVMe storage for models, vector index and document cache
- RAG over team documents, with answers that cite the source file
- Private chat assistant with no calls to external AI services
- Fits standard office power and cooling in most cases; we confirm during the site assessment
Ideal for
- A legal practice group searching its own precedents and templates
- A finance or compliance team summarising internal reports
- An engineering team running a private coding assistant
- A proof of concept before a department-wide rollout
Deployed by our partners
- Site assessment: power, cooling, rack space, network and security review of your server room or data centre
- Installation: racking, cabling, burn-in and acceptance testing on your premises
- Model deployment: open-weight LLMs selected, quantized where useful, and served on your hardware
- RAG and document integration: connectors to your file shares, document management and knowledge bases
- Access control: single sign-on, role-based permissions and audit logging
- Monitoring: hardware health, utilisation and model-serving dashboards with alerting
- Support SLA: remote and on-site support, spares and updates under an agreed service level
Typically 25–200 users · Most requested
Department bundle
Shared AI for a whole department, with several use cases on one platform.
- Typical users
- 25–200 users
- Typical models
- Open-weight LLMs up to ~70B parameters
- GPU class
- 4–8 data-centre GPUs
- Storage
- NVMe array
- Form factor
- Single rack server
What’s included
- A 4–8 GPU server with data-centre GPUs and high-bandwidth memory
- Enough GPU memory to serve open-weight models up to ~70B parameters
- NVMe storage for models, embeddings and document indexes
- Multiple use cases on one platform: chat, RAG, coding assistant and document processing
- SSO integration with your existing identity provider
- Role-based access so each team sees only its own document collections
- Rack power distribution and cooling review for sustained full load
Ideal for
- A hospital department or clinic group working with patient records
- A bank operations, risk or compliance division
- A government department handling sensitive internal or citizen data
- An engineering or operations division with large document archives
Deployed by our partners
- Site assessment: power, cooling, rack space, network and security review of your server room or data centre
- Installation: racking, cabling, burn-in and acceptance testing on your premises
- Model deployment: open-weight LLMs selected, quantized where useful, and served on your hardware
- RAG and document integration: connectors to your file shares, document management and knowledge bases
- Access control: single sign-on, role-based permissions and audit logging
- Monitoring: hardware health, utilisation and model-serving dashboards with alerting
- Support SLA: remote and on-site support, spares and updates under an agreed service level
Typically 200+ users
Enterprise bundle
Organisation-wide private AI on a rack-scale cluster you own and control.
- Typical users
- 200+ users
- Typical models
- The largest open-weight LLMs, plus fine-tuning
- GPU class
- Multi-node GPU cluster
- Network
- 400G/800G fabric
- Form factor
- Rack-scale, liquid-cooled
What’s included
- A rack-scale multi-node GPU cluster
- Liquid cooling sized for high-density racks
- UPS and intelligent PDUs for protected, metered power
- 400G/800G network fabric between nodes
- Capacity for the largest open-weight models and for fine-tuning on your own data
- Multi-tenant serving with per-department quotas and isolation
- Shared NVMe storage tier for models, datasets and indexes
Ideal for
- Banks and insurers rolling out AI across business lines
- Hospital groups and health authorities
- Government entities and critical infrastructure operators
- Enterprises that want to fine-tune models on proprietary data
Deployed by our partners
- Site assessment: power, cooling, rack space, network and security review of your server room or data centre
- Installation: racking, cabling, burn-in and acceptance testing on your premises
- Model deployment: open-weight LLMs selected, quantized where useful, and served on your hardware
- RAG and document integration: connectors to your file shares, document management and knowledge bases
- Access control: single sign-on, role-based permissions and audit logging
- Monitoring: hardware health, utilisation and model-serving dashboards with alerting
- Support SLA: remote and on-site support, spares and updates under an agreed service level
Sizing
Which bundle fits?
The right size depends on how many people use it at once, which model sizes you need, and how many documents you index. Our sizing guide walks through each factor.
Request a quote
Request a bundle quote
Tell us your users, use cases and site. We reply within one business day with a right-sized proposal. No obligation.